FOR NEOCLOUDS AND INFERENCE PROVIDERS
Turn more of your GPU capacity into billable inference.
Cogniware helps AI infrastructure providers generate more usable inference from their hardware. Improve throughput and latency, raise utilization, reduce power and operating overhead, and manage inference as a service.
The result: lower cost to serve, stronger margins, and more capacity to sell without adding infrastructure at the same rate.

IMPROVE THE ECONOMICS OF EVERY TOKEN
More usable capacity. Lower cost to serve.
Cogniware helps you deliver superior unit economics from your existing capital infrastructure. That improves competitiveness and expands margins.
Use more of your GPU fleet
Keep expensive accelerators doing productive work instead of sitting idle, fragmented, or under-filled.
Generate more goodput
Increase inference delivered within latency, reliability, and quality targets, not just raw tokens per second.
Reduce power per unit of work
Better utilization and less redundant compute can lower the energy required to produce useful inference.
Carry less SLA headroom
More predictable performance can reduce the spare capacity providers hold back to protect premium service levels.
Reduce operating overhead
Centralized optimization and control reduce the need to hand-tune every model, endpoint, and workload as conditions change.
MANAGE INFERENCE AS A PORTFOLIO
One control plane instead of a collection of GPU servers.
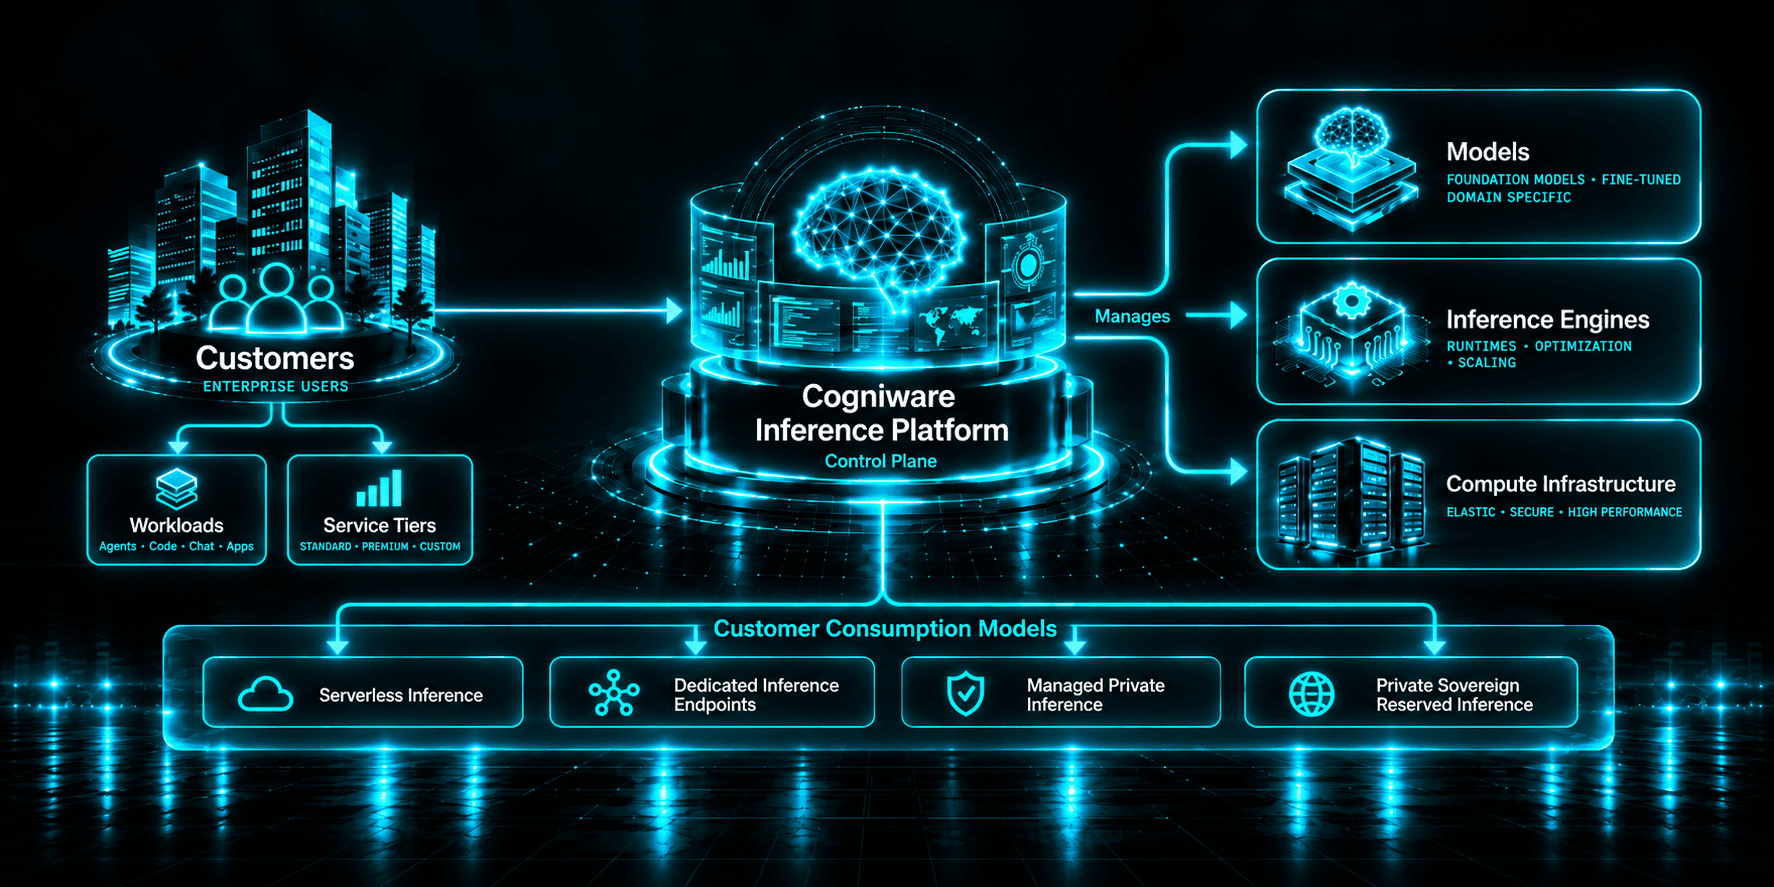
Cogniware gives providers one place to coordinate demand, capacity, service levels, and performance across the inference business.
Prioritize
Apply operating policy by customer, workload, or service tier.
Route
Direct requests to available capacity and the right model or execution path.
Observe
See service-level signals, GPU and KV telemetry, utilization, and where concurrency is building.
Optimize
Apply performance modules to improve goodput, throughput, TTFT, and end-to-end latency for eligible workloads.
Roll out safely
Use shadow, canary, enforcement, kill switches, and rollback rather than making platform changes all at once.
Scale consistently
Use the same control, evidence, and operations model across serverless pools, dedicated endpoints, and private deployments.
The rise of Inference-as-a-Service
EXECUTIVE GUIDE
The Rise of Inference as a Service
Understand the forces driving this model to become the primary way enterprise inference is delivered and consumed. The paper examines provider economics, the shift toward open-weight models, service design, and how serving efficiency can turn GPU capacity into a higher-value inference business.
KEEP THE STACK EFFICIENT AS THE WORKLOAD CHANGES
Inference is dynamic. Your operating model should be too.
Adapt to workload shape
Different request sizes, context lengths, concurrency levels, and service tiers create different bottlenecks. Cogniware gives operators a common layer for responding to those changes.
Support changing model mix
Run leading open-weight models and fine-tuned variants without tying the service business to one model family or release cycle.
Preserve hardware choice
Operate across heterogeneous GPU infrastructure and supported inference engines, giving the business more flexibility as price, availability, and accelerator generations change.
Reduce constant expert tuning
Central policy, observability, validation, and optimization reduce the need for specialists to reconfigure every endpoint independently.
INDEPENDENTLY TESTED
More capacity when concurrency starts to matter.
The Cogniware Inference Platform enables you to punch above your weight with inference capacity, while your service remains responsive and reliable under load.

~24% higher sustained throughput
Against the OCI vLLM baseline in the published Artificial Analysis test.
~30% higher peak throughput
More output from the same eight-H200 class of system in the tested configuration.
0.73 sec median TTFT at 1,024 concurrency
Versus 18.17 seconds for the OCI vLLM baseline, while Cogniware maintained at least a 92% response rate across the tested range.
A PLATFORM FOR A SERVICE BUSINESS
Stay optimized at all times, without making the service harder to operate.
Cogniware helps you deliver more consistently, operate with more flexibility, and improve resilience without impacting the quality of inference output.
Model and engine flexibility
Support leading open model families and adapter-based integration with engines including vLLM, SGLang, TensorRT-LLM, and Triton, certified by deployment profile.
GPU vendor flexibility
Use one control layer across heterogeneous infrastructure so the business can respond to accelerator cost, supply, and workload fit.
Scalable operations
Apply consistent policy, routing, observability, and rollout controls as customers, endpoints, and capacity grow.
Built for resilience
Timeouts, circuit breakers, bounded retries, backpressure, graceful degradation, and visible fallback behavior support production service levels.
Faster diagnosis
Metrics, traces, safe logs, SLO signals, GPU telemetry, and incident summaries give operators a clearer view of what is happening.
Preserve model output
Performance optimization can improve execution without changing baseline model output. Model or routing changes happen only when you choose to introduce them.
See what Cogniware can do for your inference economics.
Start with your current models, workloads, service levels, and GPU fleet. We will help you establish the baseline, identify where usable capacity is being lost, and measure the performance and cost impact of Cogniware.
