INFERENCE INFRASTRUCTURE, RE-ENGINEERED
Cut your AI spend by 50%
Cogniware maximizes the impact of every GPU.

OWN YOUR INFERENCE
Cogniware is the easiest, most efficient way to run your own inference — in the cloud or on premises.
INDEPENDENT VALIDATION
The benchmark is just the beginning.
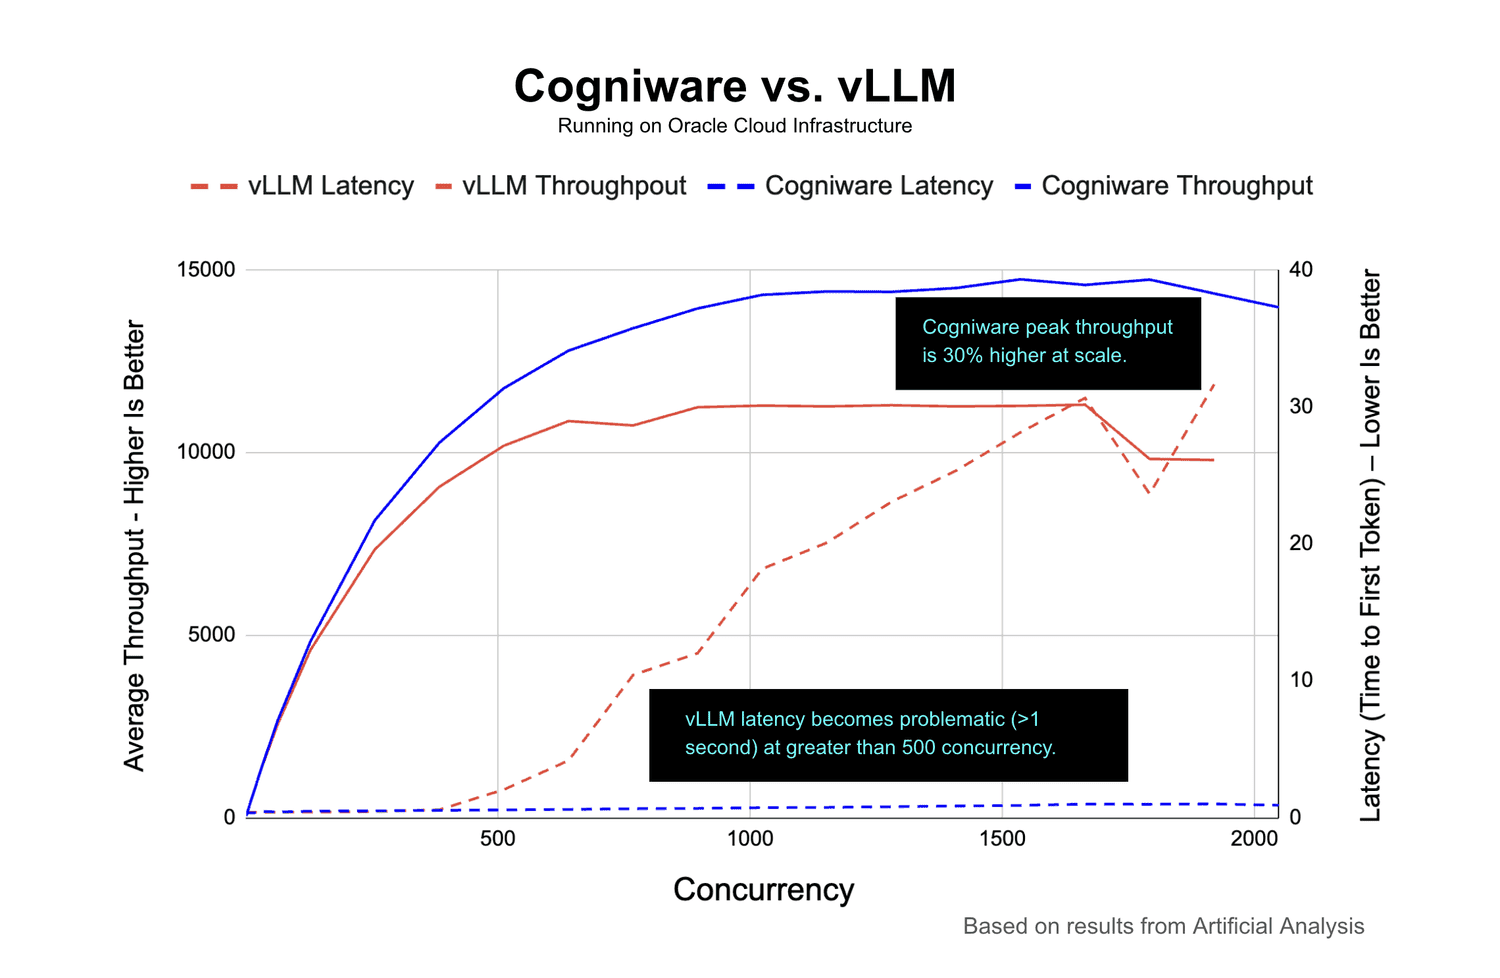
Independent benchmarking from Artificial Analysis proves it. The Cogniware Inference Platform delivers more throughput, lower latency, and is more stable at higher concurrency than the leading inference engine alone.
8× H200
TO 2,048 CONCURRENCY
PLATFORM INDEPENDENCE
Choose your compute.
Cogniware enables compute platform independence. Run scalable AI workloads on CUDA, x86, x64, Stream, and Tensor Core processors.
NVIDIA
INTEL
AMD
QUALCOMM
MODEL PORTABILITY
Choose your model.
Choose any model from the open-weight AI leaders. Or bring your own model with fine-tuning and guardrails.
META

MISTRAL
OPENAI

QWEN

DEEPSEEK
COGNIWARE SERVICES
Optimize your inference stack from models to megawatts.
Make every layer of your AI infrastructure work harder — from model routing and caching to power, cooling, and capacity planning.


MORE CAPABILITY, LESS INFRASTRUCTURE
The Cogniware impact.
READY TO MAX YOUR CAPACITY?

